Arctic Tracker
Conservation intelligence for Arctic species trade
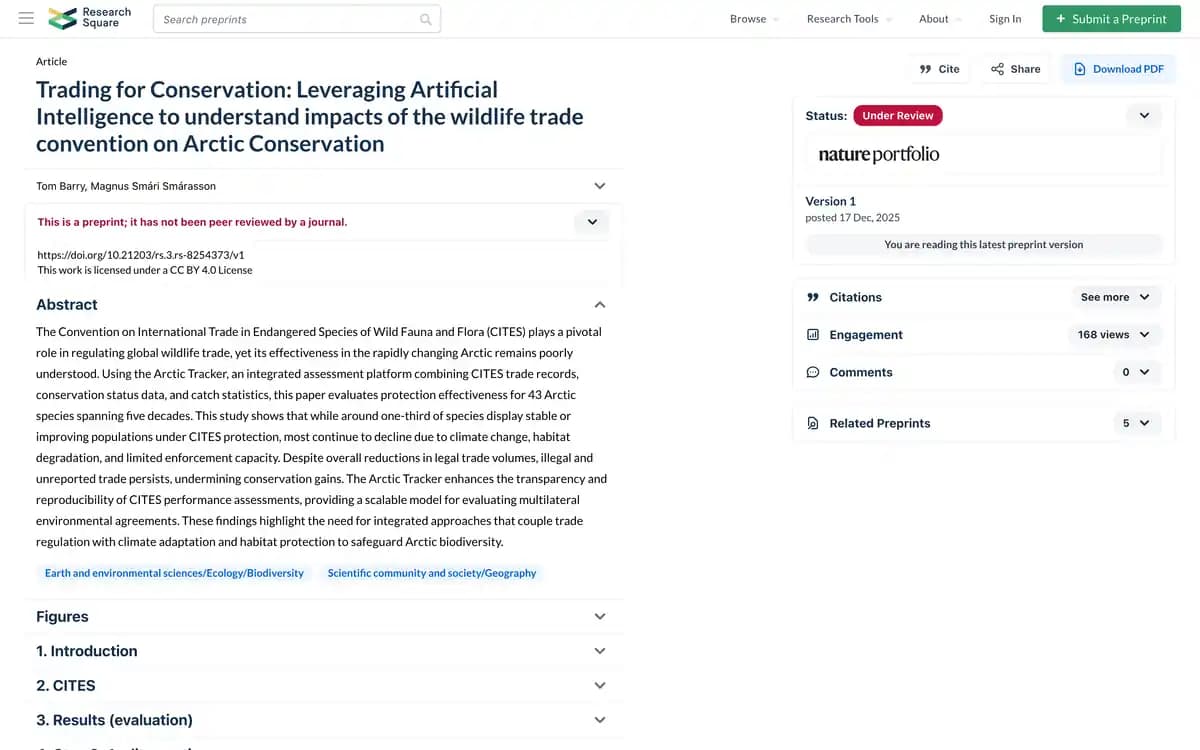
A data platform integrating 492,095 CITES trade records, IUCN assessments, and illegal seizure data for 43 Arctic species. Research Square preprint by Tom Barry and Magnus Smári Smárasson (17 December 2025).
The Challenge
Conservation data for Arctic species is scattered across CITES trade databases, IUCN assessments, CMS listings, and NAMMCO catch records. No single platform integrates these sources, making it nearly impossible to assess whether trade conventions are actually protecting Arctic wildlife. Researchers rely on fragmentary data — individual trade records, single-species assessments — without the cross-referencing needed to detect systemic patterns. Meanwhile, climate change accelerates threats faster than traditional assessment cycles can track.
The Approach
Arctic Tracker unifies five international data sources into a single analytical platform. Python ETL pipelines process raw data from CITES (492,095 trade records), IUCN (370 assessments in the 1 September 2026 deposit), CMS (92 listing records), and NAMMCO (958+ catch records), loading into a PostgreSQL database across 24 tables in the deposited schema (1 September 2026). The React/TypeScript frontend provides species-level detail pages with tabbed views across all data dimensions. Interactive visualizations built with Plotly support the research paper. An MCP server enables AI assistants to query the database directly for real-time cross-referencing during research.
Outcomes
Arctic Tracker is a data platform and analytical environment built to answer a question that conservation policy has skirted for decades: are international trade conventions actually protecting Arctic wildlife? The platform integrates 492,095 CITES trade records, 370 IUCN assessments in the 1 September 2026 deposit (349 global and 21 European regional assessments), 919 compiled seizure records, of which 225 passed the Tracker’s taxon check (4 November 2026), and NAMMCO catch statistics for 43 Arctic species — making visible what was previously scattered across incompatible international databases.
The project is a collaboration with Dr. Tom Barry at the University of Akureyri. A preprint — Trading for Conservation — was posted on Research Square on 17 December 2025, by Tom Barry and Magnus Smári Smárasson (names as listed). The current 492,095-record count is from thearctic.is on 4 November 2026; the Tracker withholds individual dataset authorship until publication. The revised manuscript was in a second round of peer review at Nature Communications as of 3 November 2026.
The Research
The study describes recorded trade and changes in conservation-status categories. It has no counterfactual comparison and does not establish the effectiveness of CITES.
This matters because conservation policy still treats trade regulation as the primary lever. The data suggests a more complex reality: protection regimes designed in the 1970s are encountering environmental pressures they were never built to address. Arctic Tracker makes these patterns visible so that evidence — not assumption — drives the next generation of conservation decisions.
Architecture
The platform comprises three components: a Python ETL backend for data processing, a PostgreSQL database with PostGIS and 24 tables in the deposited schema (1 September 2026), and a React/TypeScript frontend.
- Backend — Python 3.12 with ETL scripts for CITES, IUCN, CMS, and NAMMCO data ingestion. Pandas and NumPy for analysis. Automated quality assessment and database auditing.
- Database — self-hosted PostgreSQL with PostGIS, 24 tables in the deposited schema (1 September 2026), covering species, trade records, assessments, catch data, illegal seizures, conservation measures, and distribution ranges. SQL tables support the analysis.
- Frontend — React 18 with TypeScript, Vite, TanStack Query, Shadcn UI, and Tailwind CSS. Species detail pages with tabbed navigation across trade, assessment, catch, illegal trade, and timeline data. Admin panel for data management.
- Visualizations — Interactive figures built with Plotly: trade patterns, enforcement analysis, partner networks, conservation status trends, status change heatmaps, illegal seizure analysis, and wild-origin trade flows.
- MCP Server — A TypeScript Model Context Protocol server connects AI assistants directly to the database, enabling real-time cross-referencing of species data during research workflows.
Data Governance
No automated scraping of unverified sources. Every record is traced to its international source database. Data quality scripts run automated audits across the full dataset.
Update — July 2026
The platform was moved off a hosted backend and onto its own infrastructure. The database now runs PostgreSQL with PostGIS on dedicated hardware, with PostgREST as the access layer, GoTrue for authentication, and independent backups. The data model, the ETL pipelines, and the frontend are unchanged — the move was about hosting and custody of the data, not about functionality.
Technology Stack
People
Resources
Lessons Learned
- Integrating multiple international databases reveals patterns invisible in any single source — cross-referencing trade with IUCN categories describes change but does not establish the effect of CITES.
- Climate change, habitat loss and national management complicate interpretation of changes after CITES listing.
- Pre-aggregation is essential for research platforms. Summary tables transformed the experience without sacrificing analytical depth.
- An MCP server connects AI assistants directly to the database for research workflows.
Related Projects
View all projects →
BORG
The University of Akureyri's hybrid AI platform, combining commercial models with on-premise infrastructure with an option for processing on the university network.
Smarason.is
A personal site moved home: Next.js 16 + Payload on its own Hetzner edge with Caddy, no cloud content service, no first-party analytics. The architecture is the philosophy — sovereignty over your own data.
Institutional Knowledge Graph
Small organisations run on invisible architecture — governance, systems, policies, dependencies that live in people’s heads. This is the complete methodology for making that architecture queryable: Neo4j, JSON-LD, SHACL, and a pipeline that is always safe to re-run.